What a Week to Be a Developer: When the Internet Breaks Your Entire Stack
What a wave of developer-tool outages teaches us about dependencies, deployment, and resilience
Full Article
Read the complete article, including examples, background, practical insights, and technical details.
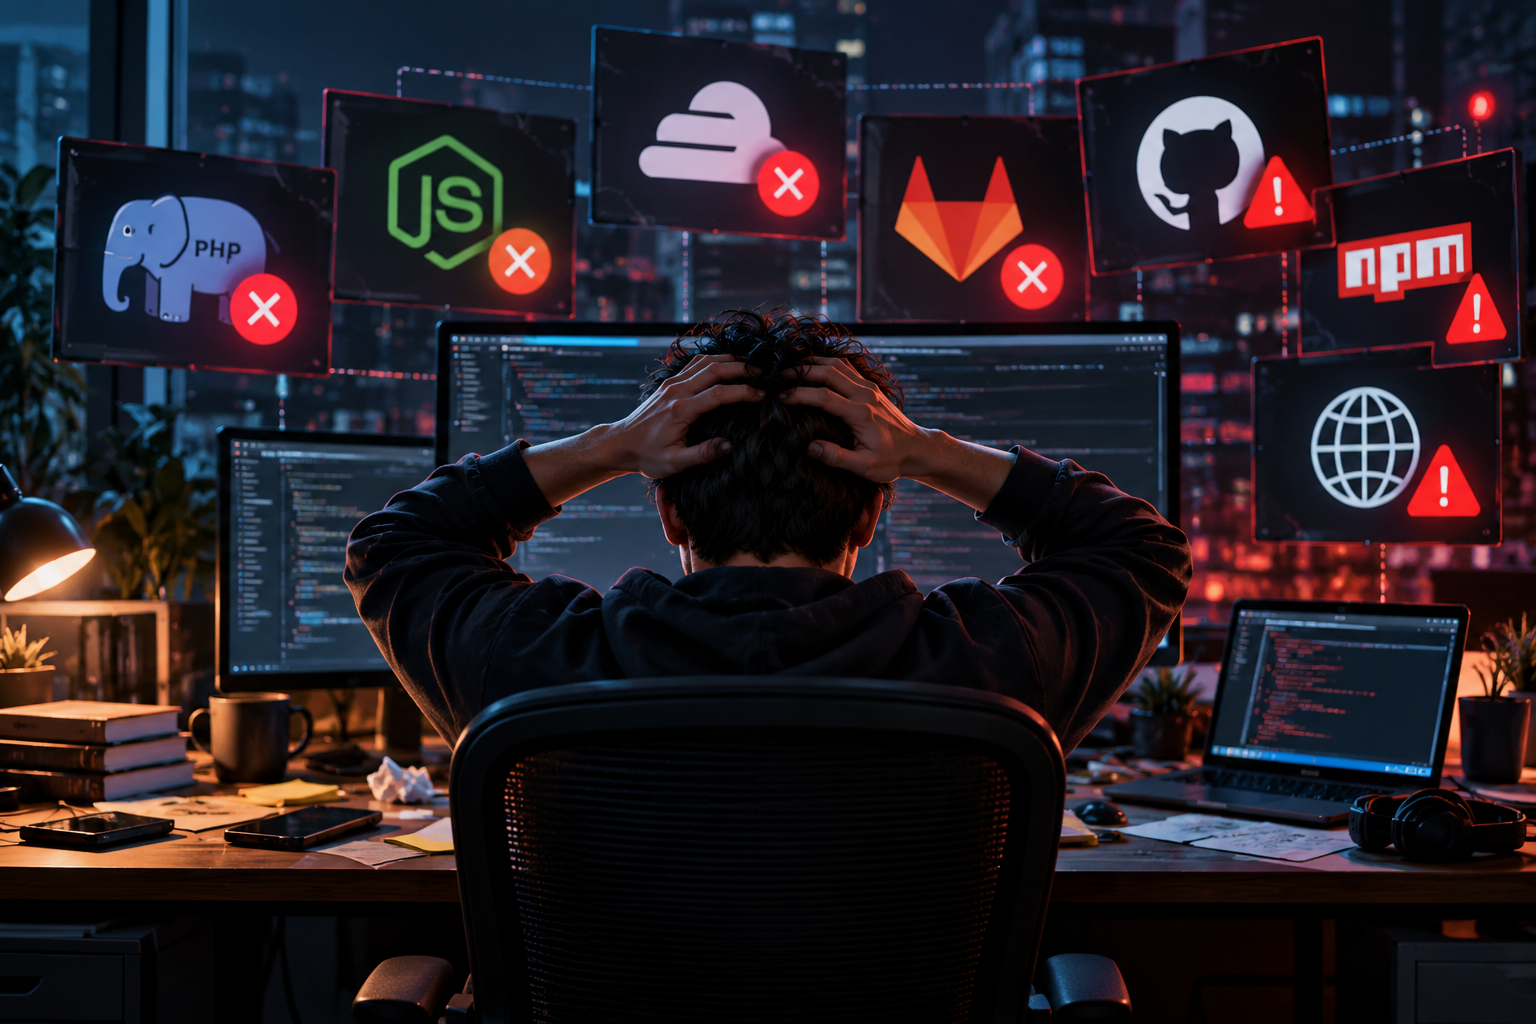
PHP down. Node.js down. Railway derailed. GitLab gone. GitHub Actions and npm degraded. And the internet seemingly crawling along.
That's the picture painted by a developer's frustrated recap of the week. These are claims from the original post, not an independently verified incident timeline. The larger point, however, is familiar to anyone who has watched a deployment stall because a service outside their control stopped responding.
At some point, git push stops feeling like a command and starts feeling like a prayer.
Modern software development depends on an extraordinary chain of external systems. You may own the source code, but your build might require a package registry, your tests might require a hosted CI runner, and your release might depend on a cloud platform's control plane. One failure can interrupt the whole process.
The Stack You Don't Actually Control
Consider a typical deployment pipeline:
- A developer pushes code to a Git hosting service.
- A CI provider starts a workflow.
- The workflow downloads dependencies from a package registry.
- Tests and builds run on hosted infrastructure.
- A deployment platform publishes the release.
Each step is a dependency. If any critical step fails, your code may be perfectly healthy while your release is blocked.
That doesn't mean every team needs to operate its own infrastructure. It means teams should know where their single points of failure are and how to work around them.
1. Cache Dependencies Before the Registry Has Problems
A temporary npm registry issue should not automatically prevent every build.
For Node.js projects, commit your lockfile and use reproducible installation commands such as:
npm ciConfigure your CI pipeline to cache the npm download cache between runs. For example, GitHub Actions supports dependency caching through actions/setup-node:
- uses: actions/setup-node@v4
  with:
    node-version: '22'
    cache: 'npm'
- run: npm ci
Important: A warm cache can reduce registry dependence, but it does not guarantee a fully offline build. Test your offline strategy explicitly, especially when native packages, installation scripts, or uncached versions are involved.
2. Know Where Your CI Runs—and Have a Manual Deployment Path
Hosted CI is convenient until its control plane or runners are unavailable.
Document the minimum steps needed to build, test, and deploy without your usual CI interface. Depending on your platform, that might mean running a local build, publishing a container image, or using a deployment CLI from an authorized workstation.
Your fallback process should still enforce essential safeguards: credentials management, tests, approvals, and a rollback plan. Manual deployment should be a documented emergency procedure, not a shortcut around security.
3. Bookmark the Status Pages You Actually Need
When an outage begins, the first question is often whether the problem is in your application or upstream.
Keep a short incident reference that includes the status pages for your Git host, CI service, package registry, cloud provider, DNS provider, and deployment platform.
Examples include:
A green status page is not proof that your specific workflow is healthy, but it is a useful starting point. Pair it with logs, synthetic checks, and your own monitoring.
4. Keep Your Code in More Than One Place
Git is distributed by design. Every full clone carries repository history, which gives teams options when a hosting provider becomes unavailable.
You can configure a second remote:
git remote add backup git@your-backup-host:team/project.git
git push backup --all
git push backup --tags
Mirror important repositories on a schedule and periodically test restoring from the mirror.
Remember that a repository mirror is not a complete platform backup. Issues, pull requests, secrets, artifacts, CI configuration, and release metadata may need separate export or recovery procedures.
5. Practice Recovery Before You Need It
An incident is the worst time to discover that nobody knows how to deploy without the normal pipeline.
Try a lightweight recovery exercise:
- Build a project with limited registry access.
- Verify that another team member can deploy using the documented fallback.
- Restore a repository from its backup remote.
- Confirm that a failed release can be rolled back.
- Record what was missing from the runbook.
These drills reveal fragile assumptions while the stakes are low.
Reliability Is a Developer Experience Feature
Outages are not only an operations problem. They affect engineering productivity, release confidence, customer experience, and team morale.
The lesson isn't to abandon cloud services or hosted developer tools. It is to avoid treating convenience as a guarantee of availability.
Know your dependencies. Cache what you can. Keep recoverable copies of what matters. And make sure your team has a safe way to ship when the usual path is blocked.
Because the next time git push turns into a prayer, preparation is what gives you another option.
TL;DR
- Cache dependencies and test whether builds can work with limited registry access.
- Document a manual deployment path that preserves security checks and rollback capability.
- Bookmark status pages and monitor your own critical workflows.
- Mirror repositories, while separately backing up platform-specific metadata.
- Run recovery drills before a real outage forces you to improvise.
Which outage hit your workflow hardest this week—and what would you change before the next one?
Comments load as you scroll…